My Service Scaling Weekend: The Science of Building Robust, Scalable Services
My Service Scaling Weekend: The Science of Building Robust, Scalable Services
It is Monday, and I survived my service-scaling weekend with my sanity intact 😮💨. So, I feel I must share my experiences and journey over the last two days.
What Is a Scalable Service?
Let me start by defining what I mean by scale in the context of this blog.
When we build software systems, there are several different lenses through which we can evaluate the architecture. A system can perform exceptionally well in one area while being poorly designed in another.
I generally think about an application through a few core architectural concerns:
- Safety: How well are your systems and data protected from external threats, internal vulnerabilities, accidental misuse and failure?
- Efficiency: How efficiently does the system use the resources available to it? Can you achieve greater throughput and better performance without simply adding more infrastructure?
- Reliability: How well does the workload continue operating when things go wrong? What happens when a server fails, a data centre loses power, a dependency becomes unavailable or an entire cloud Availability Zone experiences an outage?
- Scalability: How well can the system accommodate changes in demand? Can it serve 100 users, 10,000 users or one million users without requiring the architecture to be fundamentally redesigned? Where are the bottlenecks, and what happens as you approach them?
- Cost: How much does the workload cost to operate, and how does that cost change as usage increases? A system that can technically handle one million users but becomes economically unsustainable at 100,000 users is not particularly well designed.
If you have studied the AWS Well-Architected Framework, you will recognise many of these concerns. AWS defines six pillars:
- Operational Excellence
- Security
- Reliability
- Performance Efficiency
- Cost Optimisation
- Sustainability
I believe scalability deserves to be considered explicitly as an architectural concern of its own.
It sits somewhere at the intersection of Reliability, Performance Efficiency and Operational Excellence.
Defining Scalability
A scalable service is one that can accommodate significant changes in demand by adding or removing capacity without requiring fundamental architectural changes, while continuing to meet its expected performance, reliability and cost targets.
That distinction is important.
Scalability is not simply:
“How many users can my application handle?”
That tells us something about the application’s current capacity.
The more interesting question is:
“What happens when the number of users increases by 10x, 100x or 1,000x?”
- Can you add more application instances?
- Can the database keep up?
- Can your queues absorb sudden spikes?
- Can your storage layer continue performing?
- Is there a component in the architecture that cannot scale horizontally?
- Does latency remain acceptable?
- Does the application remain available while capacity is being added?
Perhaps just as importantly: do the economics of the architecture still make sense at that scale?
A well-designed, scalable system should be able to scale up when demand increases and scale down when demand disappears.
It should do this without breaking, without requiring heroic intervention from the engineering team and without producing an infrastructure bill that grows disproportionately to the value being delivered.
The Science of Building Robust Technology
Without sharing any confidential project information, the task we were dealing with was substantial.
We needed to build a highly reliable production environment capable of handling thousands of transactions per minute across multiple interconnected microservices.
That sounds like a scaling problem.
But scaling itself is not really the hard part. Scaling is software engineering.
The difficult part is getting the foundations right so that you can design, observe, test and continuously improve a system until you are confident that it will behave predictably under load.
This is where things often become complicated.
When those foundations are not in place, something that should be a reasonably straightforward engineering exercise can quickly become a monster of a project.
Before you can seriously talk about scaling a production workload, a few things need to exist.
1. Observability
You cannot scale what you cannot see.
When you are working with a distributed architecture, looking at CPU utilisation on one server tells you almost nothing about the health of the overall system.
In our case, there were many interconnected services, and the load was not distributed evenly between them:
- Some services received significantly more traffic than others.
- Some workloads were synchronous.
- Some were asynchronous.
- Some relied on queues.
- Some operations were processed in batches.
- Others depended on downstream services that could themselves become bottlenecks.
This means the system cannot simply be viewed as one application receiving a certain number of requests per second.
It is a network of components, each behaving differently under load.
You need to be able to answer questions such as:
- Which service is currently receiving the most traffic?
- What is the request rate for each service?
- What is the latency at the API level?
- Are requests waiting in queues?
- How quickly are those queues being consumed?
- Are database connections approaching their limits?
- Are containers running out of CPU or memory?
- Are downstream dependencies slowing the system down?
- Are errors increasing as traffic increases?
- Are we scaling fast enough to meet the incoming demand?
You need those answers in real time.
You cannot realistically jump from dashboard to dashboard, service to service and log file to log file while trying to understand what is happening inside a distributed system.
We needed centralised observability.
Metrics, logs, traces, application performance, infrastructure capacity and service health needed to come together in one place so that we could see how the entire platform behaved as load moved through it.
Observability becomes even more important during load testing because it tells you something that the load-testing tool itself cannot:
Why is the system slowing down?
A load test can tell you that response times increased from 100 milliseconds to three seconds.
Observability tells you whether that happened because of CPU saturation, database contention, exhausted connection pools, queue growth, network latency, application locks, memory pressure or a completely unexpected dependency.
2. Infrastructure as Code
This should be basic software engineering by now, but I am constantly surprised by how many production environments are still effectively click-built.
- Someone created a server.
- Someone changed a security group.
- Someone increased the CPU.
- Someone added an environment variable directly in the console.
- Someone modified a load balancer.
Six months later, nobody remembers exactly what changed, why it changed or whether the development, staging and production environments are still configured in the same way.
That is configuration drift.
Configuration drift becomes dangerous when you are trying to understand system behaviour at scale.
Infrastructure should be reproducible.
Whether you use AWS CDK, Terraform, CloudFormation or another Infrastructure as Code tool, your infrastructure configuration should form part of your software engineering process.
More importantly, there cannot be a hard organisational wall between development and DevOps.
The application developer needs to understand how the application is deployed.
Developers need to understand container limits, environment variables, health checks, networking, connection pools, queues, scaling policies and the infrastructure assumptions surrounding their code.
Likewise, whoever is responsible for the infrastructure needs to understand what the application actually does.
They should be able to answer the following questions:
- How does the application use memory?
- How does it open database connections?
- Which operations are CPU-intensive?
- Which endpoints are expensive?
- Which workloads can be processed asynchronously?
- What happens when an instance receives a termination signal?
- How long does the application take to become healthy?
These are not purely “developer” questions or purely “DevOps” questions.
They are systems engineering questions.
In our team, development and DevOps responsibilities are deliberately closely aligned—and, in many cases, handled by the same engineer.
That removes an enormous amount of unnecessary communication overhead.
When development and infrastructure teams operate as completely separate worlds, small misunderstandings between them can introduce surprisingly large architectural problems.
At scale, those problems become expensive very quickly.
3. Testing, and Then More Testing
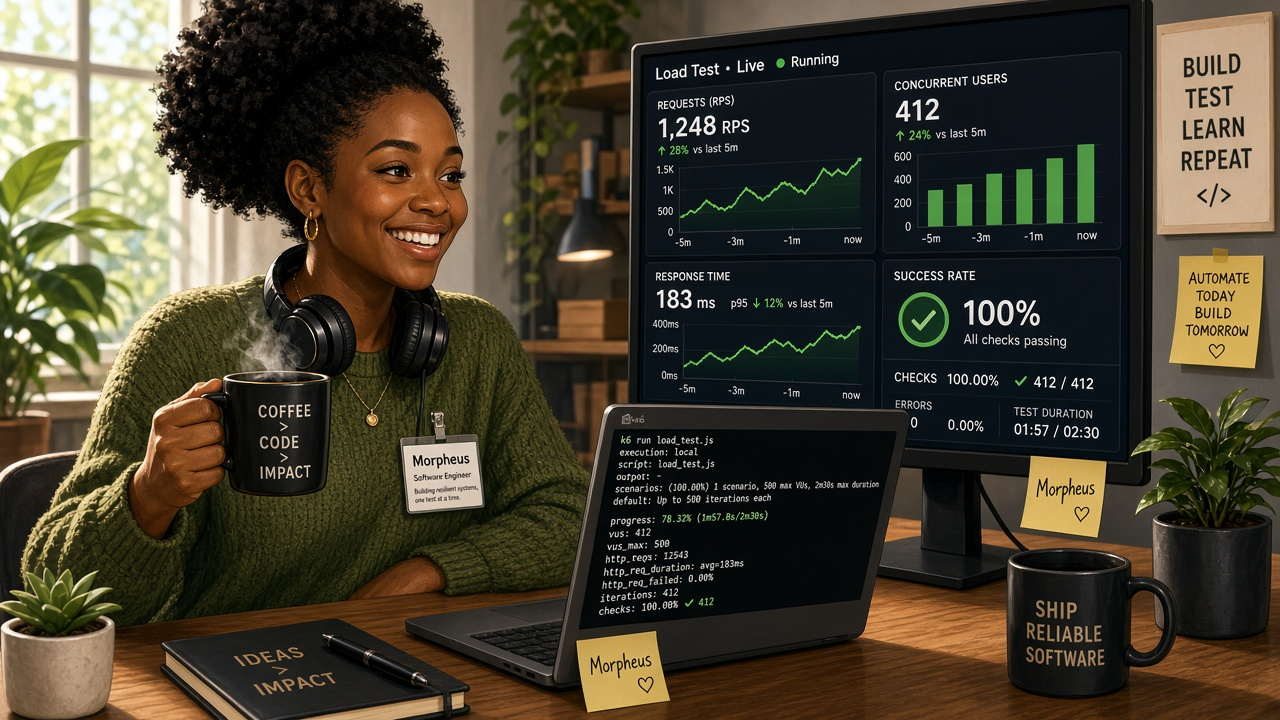
How do you know how your system will behave under heavy load?
You test it. 🥹
There is really no substitute.
Architecture diagrams, CPU calculations, instance specifications and theoretical throughput estimates are useful, but production systems rarely behave exactly as you expect them to.
You absolutely do not want your real users to become your first serious load test.
The process is straightforward, but disciplined:
- Deliberately push the system.
- Observe what happens.
- Change something.
- Test it again.
This becomes an iterative engineering process in which load testing and rightsizing work together.
You might start with a particular CPU and memory configuration.
Run the test.
Measure throughput, latency, error rate and resource utilisation.
You might discover that the CPU is hardly being used, but the database connection pool is exhausted.
Or that the application is using significantly more memory than expected.
Or that adding more application instances does absolutely nothing because the real bottleneck is somewhere downstream.
You make the adjustment.
Then you run the test again.
And again.
And again.
Eventually, you begin to understand the relationship between:
Load → resource utilisation → scaling behaviour → system performance → cost
That is where things become interesting.
The objective is not simply to find a configuration that survives your biggest load test.
The objective is to design a system that can move efficiently through a very wide operating range.
In an ideal architecture, the same platform should be capable of operating economically with very little traffic, scaling progressively as demand increases, handling extreme peaks and then scaling back down when the traffic disappears.
I like to think about the target as:
1 → 10 → 100 → 1,000 → 10,000 → 1,000,000 → and back again
Ideally, none of those transitions should require a human being to log into the infrastructure and start changing things.
That is where scalability becomes much more than simply adding more servers.
You are building a system that can observe demand, absorb demand, respond to demand and recover from demand automatically.
Getting there requires testing.
A lot of testing.